Strands: AI That Remembers
an introduction to the strand methodology
The problem
A common frustration when developing anything complex is that the agent has to be taught about the project over and over again.
It is tempting to keep a session open so the context is not lost. The cost per turn then climbs, because the whole context goes back up each time you send a message. That is how these agents work. Caching makes the re-read tolerable, but an interruption (lunch!) can be very expensive. If the context gets huge it will be compacted, which is lossy and cannot be edited: there is no reaching into a summary to correct what it got wrong.
Writing documentation might help, but only if the agent reads it, and that is not something you can count on.
Which is where strands come in. A strand (as in a strand of thought) is a line of work, developed over time and kept clear of the others so that it does not tangle with the rest. The memory lives outside the session, in git, written in prose a human can read and edit.
Sessions are precious, but noisy. I back mine up and index them in an OpenSearch database so I can use a search engine on them. But they are historical, not current: a record of what happened on one day. The strand is the working memory, the curated source of truth for an area of work.
The archive of transcripts allows the human and the agent to find when something was decided, or at what time a discussion happened and from that the state of the git repos.
The unit between a repo and a session
A strand is an area of concern which specialises an agent. It might span several repos, or part of one. It contains a brief for the strand, and curated memory.
Each one is a directory of plain files, itself held in a strands repository:
CLAUDE.md (or the vendor equivalent). The mission. What this strand is, which repos it spans, how a session should open.
STATE.md. The durable memory. What exists, what is pending, what was decided and why. Deliberately not a log: it gets edited down.
IDEAS.md. An inbox for short notes, proposals or observations. It can be appended to freely using the idea script by humans or agents and triaged by the strand.
dirs. The working directories this strand needs open.
This website is developed mainly using a strand called "mywebsite". Here's an example from the STATE.md:
## Rules and traps

Each of these was learned by getting it wrong once.

- deploy zips the working tree, not HEAD. Another session's
  uncommitted edit goes live while the build stamp records the
  committed hash. Look at git status before deploying.
- boto3.client() costs ~0.14 s. Never build one per item or
  per invocation; use the cached s3_client().
- Replace an image at a new S3 key, never new bytes at the old
  one. The S3 host is outside the Cloudflare zone, so the old
  picture stays cached for 7 days.
- Check before asserting what a route serves. This strand
  once claimed / served the CV on the strength of an old line
  here, and a redirect was nearly built on it.
Each line is a mistake that was made once and need not be made again. The detective story behind each one has been cut: it is in git history and the session archive. The result is to the point, economical with context and human readable.
A cut-down version of the method is public, ready to try: github.com/PeterGrecian/ai-strands. It holds the idea and its anatomy, a template of the files a strand needs, and one small command that scaffolds them, starts the agent in one, and commits at the end. It has no dependencies, and a test that fails if that ever stops being true. Nothing in it is specific to my machines.
Example strands
mywebsite. This website is unusual as it uses API Gateway/Lambda rather than Apache or nginx. There is terraform code for standing it up, but critical Python code with testing to develop and maintain.
astro-pipeline. Turns raw sensor frames into calibrated, catalogued, quality-scored data, across several machines.
astro-storage. The storage lifecycle of every camera stream (squash, ship, retain) held as one system rather than per camera.
ansible. Changes hosts. Applies fleet configuration and fixes the drift that accumulates between applications.
monitoring. ansible configures hosts (Raspberry Pis, servers etc) so they ship logs to the OpenSearch cluster. logwatch raises alerts, and the monitoring strand diagnoses them and messages fixes to ansible. Ansible and monitoring work in parallel but have a strict split of responsibilities.
sessions. Archiving and indexing session transcripts. Also, a tool for searching sessions.
super. The house tooling: small command-line
tools every strand shares, such as secrets,
resolve-host, trash and
idea, and the global context file every session loads,
with the conventions they all follow. An agent is told to look for a
house tool before writing a new helper, so the estate grows one tool
per job rather than a copy in every repo.
towhom. Owns no code at all. Reads across every other strand and holds the whole-estate picture, and the single ordered backlog.
The loop
Say you have an hour and you want to spend it on this site's image caching. You do not open a chat and start explaining what the site is, which framework it is not built on, and what you tried last month. You start the strand that already knows:
$ strand mywebsite
That is the whole entry. The launcher moves into the strand's directory, loads the mission and the state file, opens the repositories this strand works across, and colours the terminal so you can see which one you are in. The agent's first words are what is pending and what was decided last time. The work starts at the second sentence rather than the fiftieth.
From there the cycle is the same every time:
- The agent triages the inbox against the state file. Promoting an idea is the cheap reversible default; dropping one is the deliberate act, because a good idea dropped is lost silently.
- Do the work. Prune the pending list while you are there, which is when you have the most context to judge with.
- At the end, document: update the state file, and the mission file if the ground has moved. Empty the triaged inbox. Commit and push. One command does all of it (document, commit, push), which is the only reason it happens reliably.
- Then clear the context deliberately, ready for the next item. Nothing is lost by starting again, because what mattered is in the state file, and the next turn is cheap instead of dear.
- Between sessions, when something occurs to you away from the work, spool it to whichever strand owns it: one line from any machine, landing in that strand's inbox for the next session to triage. It is the cheapest way to stop a thought dying in a terminal that is about to be closed.
The discipline is in the documenting. A state file that is never pruned decays into a second inbox, and then into noise.
Improving, not degenerating
A long conversation gets worse as it runs. More accumulates, less of it matters, and the part worth having is harder to find. A strand moves the other way. Every visit prunes the state file, so what survives is what turned out to matter, and the strand gets sharper about its own subject each time it is used.
When one area needs more depth than the strand should carry, it can be forked off into a strand of its own. That keeps each of them focused, and keeps material that has no bearing on the question out of the agent's context. Irrelevant detail does not sit there harmlessly; it blunts the answers.
How to save money
Don't use a weaker model. Savings come from using a strong model efficiently. Most of what makes an agent expensive is rediscovery: working out what this is, what was decided and why, before it can start on anything. That cost is incurred at the start of every conversation if you don't use strands. The context at the beginning of a session with system prompts etc is about 35k tokens. 5k tokens spent briefing the agent on its role and giving it subject knowledge are tokens well spent.
Effort (/effort) is the control to use. When
planning, high effort and solution exploration is needed to examine
the issues thoroughly. When coding, decisiveness and focus is
needed: medium or low effort.
By the way, because my strands run sessions in tmux, agents and scripts can write to
the command line in this and other sessions and control switches
like this, and /clear too, which is powerful.
This is where the files pay for themselves a second time. Effort is, in the end, the model working out what it has not been told. Give it the architecture, the conventions and the last six decisions in writing, and there is simply less left to derive, so the same task genuinely completes at a lower setting, rather than appearing to and failing later. Context substitutes for reasoning. That is the saving, and it compounds, because the work recurs.
Below all of that sits the rung worth aiming for: no model at all. Anything a strand has learned to do the same way every time can be written down as a script, and then it costs nothing to run.
Strands are model and vendor agnostic. I do have translators and filters for sessions which convert between the different vendor JSONL outputs, but strands themselves have been used with Claude, Gemini (agy) and Copilot. So a second backend can be put on the same question (sometimes deliberately adversarially, to argue against the first) and it arrives already knowing what it is looking at. A reviewer who has to be briefed from scratch is not worth the trouble. One who reads the state file and then disagrees with you is.
The end of a keeper
A keeper that does its job well can eventually stop needing to be an agent at all. Once the subject is understood well enough, what the strand does can be written down as a deterministic script and added to the tools, where it runs the same way every time and costs nothing to call. The strand is then archived rather than deleted, and can be revived if the subject turns out to have more in it.
Being replaced by a script is a success for a keeper. Anything that can run deterministically should.
Running them
What this needs is a terminal coding agent (Claude Code, or Gemini's equivalent) rather than an assistant living inside an editor. That is a working requirement, not a preference, and it follows from wanting more than one strand at a time.
An agent embedded in an IDE is singular by construction: one window, one project, one conversation, and a second one means a second window pretending to be a second you. A terminal agent is just a process. Seven can run at once, each already in its own directory, on its own mission, in its own colour, and none of them waiting on the others.
It also puts the tools the right way round. The agent is not a panel inside the editor; the editor is one of the things the agent can open. It brings up a file it wants you to look at, an image viewer on the frames it has just produced, a browser at the page it has just deployed. Anything you can start from a shell is available to it, which is a much larger set than any plugin interface offers.
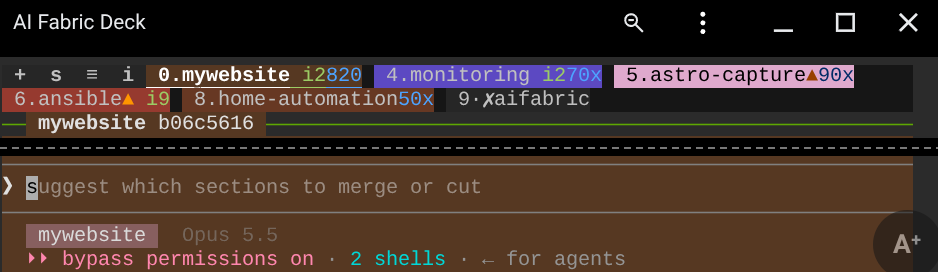
Several strands at once wants a board. Each live strand is a labelled pane, so you can see which are working and drop into any of them. Work is not serialised behind one conversation.
And they talk to each other. A strand can send another a message: a spool that persists until the recipient next opens, and a doorbell that wakes one that is already running. That matters because work constantly turns up things belonging somewhere else. Routing a finding to the strand that owns it beats leaving it in a transcript, where it dies.
The launcher and the board are conveniences, not requirements. A few terminal windows and the files themselves are a perfectly good first step, and the method works before any of the tooling does.
Letting the operating system do the guarding
Agent tools ask you to approve actions one at a time. In practice that is a bad bargain: either you read every prompt, which is laborious and slows the work to a crawl, or you stop reading them, which is worse. The usual endpoint is turning permissions off altogether. Neither a prompt you no longer read nor a bypassed check is a boundary.
Order makes something better possible. Because a strand is a durable, named unit rather than an ephemeral conversation, an identity can be attached to it, and then the operating system does the guarding, with file ownership and sudo deciding what an agent can reach. That is fine-grained, standard, auditable, and it holds whether or not anyone is paying attention.
So a strand can run as its own operating-system user rather than as you. Its processes, caches, temporary files and uncommitted working state are its own, so one strand cannot quietly disturb another's, and whatever it does is attributable in the process table.
Groups are deliberately coarser than accounts. A group marks a trust zone, not a project: everything personal in one, anything confidential in another. Per-project groups were considered and rejected: they add synchronisation friction, leak internal names into shared tooling, and buy almost nothing over a clean boundary between zones.
The identifiers are allocated from one registry and shared between machines, so a file carried from one estate to another keeps its ownership instead of arriving as somebody else's.
The tools around it
The files are the method. A set of small tools keeps the habit cheap enough to actually follow, and most of them do one thing.
Running a strand
aicli. Opens a strand: moves into its directory, loads the mission and state, opens its working directories, colours the terminal.
strands. Lists them, marking which are live, and creates new ones from a template.
strand-ps. Which strands are running, and where.
panedeck, pane. The board: every live strand as a labelled pane, and the verbs to drive one from another.
forkterm. Forks a session into a peer in its own window, either warm or briefed cold into another strand.
Working in one
idea. Spools a thought into a strand's inbox from anywhere, without stopping what you are doing. It commits and pushes itself, so nothing is lost to a closed terminal.
dcp. Document, commit, push. One command at a checkpoint: update the state file, commit, push.
resume. Writes the standing summary at the top of a state file, so a fresh session knows where it came in.
Talking between them
strand-mailbox. The spool. A message waits here until the recipient next opens, which is the half that survives a closed session.
ding. The doorbell. Wakes a strand that is already running, for when the moment matters more than the durability.
Remembering
sessions. Every transcript indexed into an OpenSearch database, searchable long after the conversation that produced it is gone.
backup. State lives in git repositories with remotes; the transcript archive is held on a server of its own. The memory outlives any one machine.
Guarding
strand-accounts. Provisions the per-strand user accounts and zone groups described above.
leak scans. Check transcripts and repositories for anything that should not travel, before it does.
Across all of them
backlog. One ordered list for the whole estate. Anyone adds to the bottom; one strand does the ranking, being the only one that sees across them all.
proposals. The drawer of arguments about what to build next, with an index that will not let one be quietly forgotten.
A sketch rather than a manual; each of these deserves its own page.
Scalable, dependable strands
A state file is the single source of truth for its area, continuously reviewed and improved as the work goes on. An LLM can read it, a person can read it, and both can edit it.
That is where the dependability comes from. A compacted conversation that has picked something up wrong cannot be reached into and corrected, and it goes on quietly steering the answers. A state file is text you can fix.
It scales because each strand carries only its own area, so adding another does not make the existing ones heavier. Sessions get cheaper too: a fresh one that reads a good state file is useful straight away, so there is no reason to keep a long conversation going past its useful life.
The tools described here are in daily use rather than written up as theory.
Putting this to work in a team
Strands work fantastically with teams using individual work in
progress strand artifacts and a shared layer,
STATE-team.md for example, which is factorised out for
sharing.
Git keeps the layers in sync, and because both are prose in git, a
contradiction between them is visible the moment it appears, rather
than during an incident.
I take consultancy work introducing and developing strands for organisations. This page is a sketch of a much more developed "fabric", and there are huge opportunities for developing it further and taming the Silicon/Carbon divide between the agents and the people working with them.